Everything in the section above is done by a brain — a service you write, in the backend you already run. It stays active for as long as the conversation does.
It runs next to your data.
Your brain is a service in the backend you already operate. It reads your database directly, with the credentials it already has, and calls the internal services it already calls.
It stays active for the whole conversation.
Conversations are stateful — you do not start afresh every sentence. Your brain stays active for the duration of the conversation, so you can keep facts in memory and build on them. We often find that an in-memory object of what the user is seeing in the app gives excellent performance and a better experience.
You control the loop.
Context management, when and how you invoke an LLM, multiple agents behind one conversation, caching, whichever framework and language you already use — all of it is yours, because you are the one running the loop.
It has a direct path to the app.
Your brain sends and receives typed events straight to and from your application. It can read what is on screen, act on it, and render a view the user has not seen before. When it matters, it directs the user’s attention by voice.
Your agent, your models, your prompts, your tools and your data stay in your backend. Text and typed events are what travel between us.
Implement that WebSocket in any technology. Speech and UI state arrive as typed events. Your reply is streaming text to be spoken, and actions for your application to perform.
All of it is already running, on our own infrastructure, on every session you open. We tune these parts to work together, so turns stay fast, tool calls land, and the inference stack underneath stays cheap to run.
Low-latency WebRTC
Transport to browser and mobile, echo cancellation, jitter buffering, voice activity detection, endpointing, barge-in.
Realtime speech
Speech to text and text to speech, on models we tune and serve on our own GPUs.
Lifelike avatars
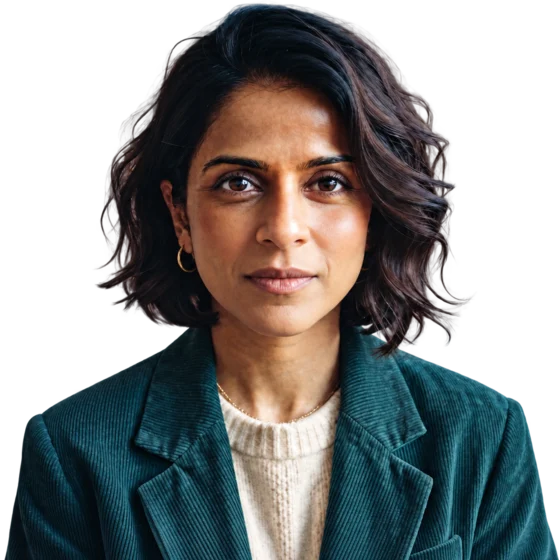
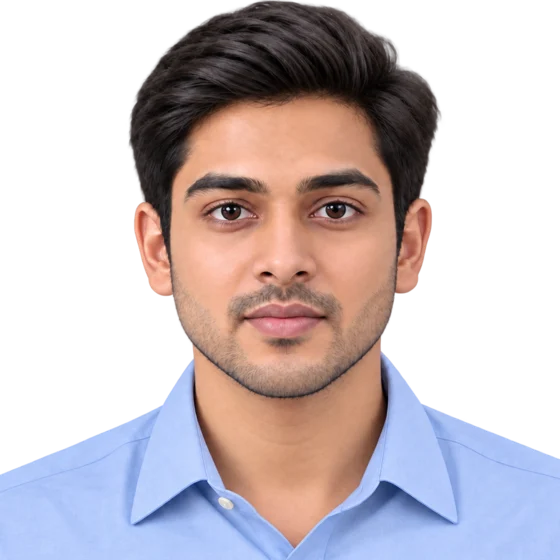
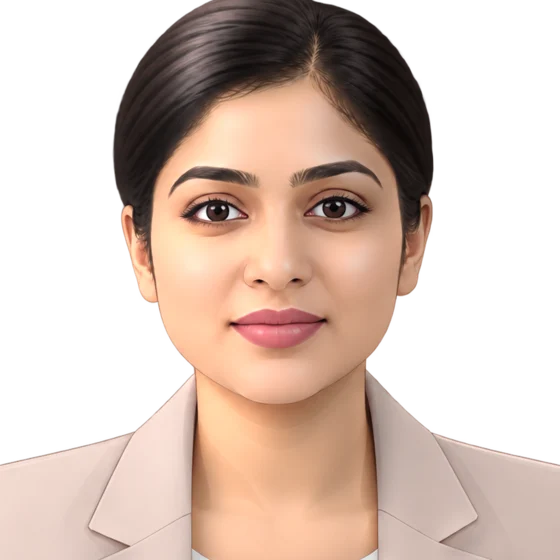
Three faces that listen, react and lip-sync, rendered on the device with no video track.
UI events and actions
Perform in-app actions and keep your agent synchronized with the screen. Typed, both directions.
Testing and evals
Verify your agent on the real wire, with no microphone, no network and no live model.
Observability
Events, transcripts, logs and usage, per session, so you can see how a session performed.
Recording
Optional, per session, with the consent gate in front of it.
Three of these can be customized for your brand.
Each one is real work on our side, so it is an enterprise engagement and starts with a conversation.
enterprise
Custom voices
We create a custom voice unique to your brand.
enterprise
BYO TTS provider
You can choose another TTS provider.
enterprise
Custom avatar
We create a custom avatar that is aligned with your brand.
The avatar is there so a person can tell, without asking, that the agent is present, that it heard them, that it is working, and what it is working on. It also speaks — for 7.2 seconds of the 28-second call below.
listening
youOpen the March report.
the report opens
youNow compare against plan.
tanyaRunning comparison.
youShow me the trend.
the trend chart is drawn
youAnd why did sales drop here?
tanyaAds were paused that week.
“here” resolves — the dipped bar turns teal
you edit the report by hand
tanyaNoted your changes.
tanyaBtw, the comparison is ready.
youPerfect, thanks.
speaking — 7.2sworkingacknowledgingthe rest of the line is listening
Three faces ship today, and more are on the way.
Each one is a photograph projected onto shallow geometry, with the parts that have to move — the eyes, the teeth, the lip line — built as geometry rather than painted. Every avatar is authored on its own, which is why yours can be drawn in your product's own idiom. Talk to us about a custom avatar →
tanyain the recording above
tusharships today
taraships today
The avatar renders on the device, from the audio and a thin stream of cues — the rig lives in your page and the frames are drawn there, which is why we do not meter it. The library is MIT and works with any pipecat agent: @voqalize/avatar on npm,voqalize-avatar on PyPI. github.com/voqalize/avatar ↗
speech
English and 22 Indian languages.
We tune and serve both speech models on our own GPUs. Your agent picks the voice and the language when the session starts.
enterprise
Cloud hosted, or deployed in your VPC.
Voqalize is cloud hosted and available as a subscription. For enterprises, we can also deploy it into your cloud VPC, with no external dependency.
where it runs
Can be deployed in your cloud VPC
Every part of the voice tier is ours, including the speech models, so all of it can run inside your VPC.
Our cloud, in the region you choose
Your cloud VPC, with no external dependency
The speech models run on your GPUs
certifications
Certified and audited
We hold the certificates below, and every privileged action is written to an audit trail you can read.
ISO 27001SOC 2DPDP compliant
Role-based access
Full audit trail
Data residency controls
forward deployed
Our engineers work alongside yours
Designing the agent, integrating your systems and tuning it once it is carrying real calls. We build and deploy with Think41 Technologies, our delivery partner.
Sign up, connect your coding agent to our MCP server, and ask it where voice belongs in what you have already built. The MCP server creates the agent record, mints the key, sets your brain_url and reads your session logs. Nothing to install.
start in your repo
Add Voqalize to your coding agent
Recommend 3 workflows where Voqalize agents can be useful in my application